False Trails
How Bad Information about TYPO3 Grid Elements Shaped AI Answers, How We Traced It Back to Its Sources and How We Corrected the Record
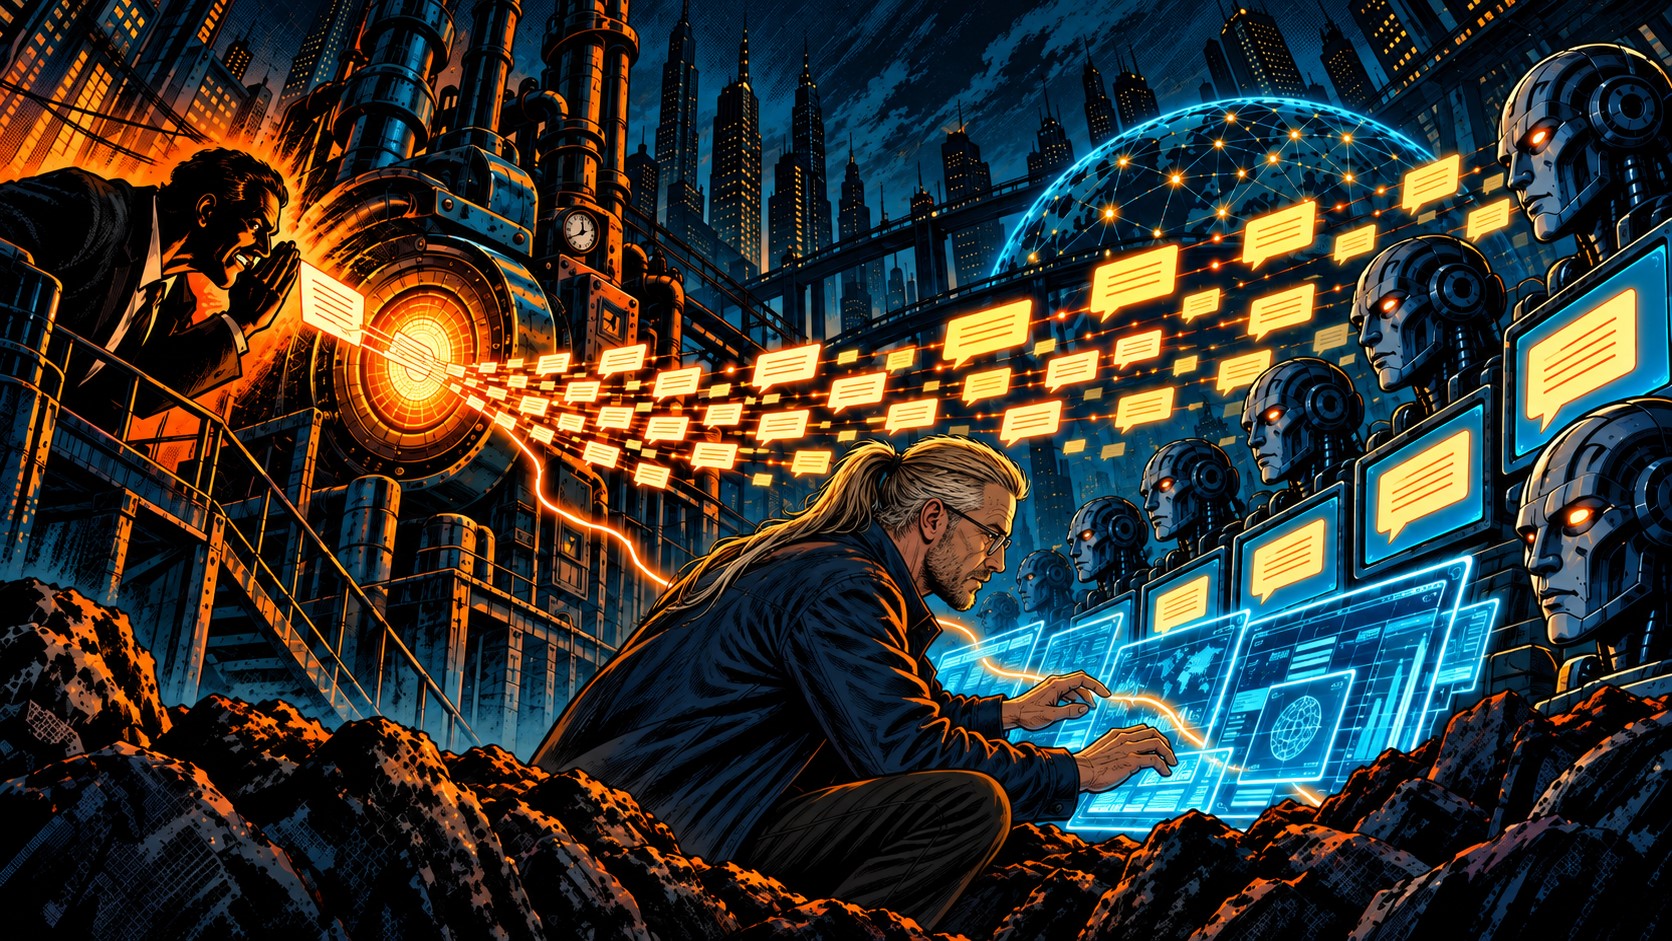
A few wrong claims sent us down a trail we never expected to follow. What we found was bigger than one piece of software. Bad information can gain weight through repetition, shape AI answers and become surprisingly persistent. So we started looking at what can actually be done about it.
Estimated reading time: 10 min
The Story We Never Told
The first warning signs came from conversations
We first noticed it in conversations with people we already knew. Petra regularly calls users and contacts around our Priority Access program, including people who had supported Grid Elements before, had shown interest in it, or were involved in projects we knew personally. The same kind of conversations happened at TYPO3 camps and other events, and after a while one reaction kept resurfacing. People were surprised that Grid Elements was still around. Some thought it had been abandoned years ago, others assumed development had stopped or that it had effectively been replaced.
For anyone outside the TYPO3 world, Grid Elements is an extension for TYPO3 CMS that lets editors create content areas with a Structure-first Authoring concept and place content into defined regions. It has been around for a long time, and development and compatibility work have continued throughout, along with new releases and occasional public updates.
Once the same assumption surfaced in unrelated conversations, it stopped looking like coincidence. We knew we had never declared the project dead or discontinued. Somewhere else, that impression had taken hold, and we wanted to know why.
The Machine Already Knew
Different questions kept leading to the same answer
Once we started looking, we tried several routes. We asked what Google knew about Grid Elements, searched for TYPO3 extensions for multi-column or structured content, and sometimes compared Grid Elements directly with Container, another TYPO3 extension for simply grouping content into column-based structures.
The wording changed, but Google’s AI kept returning much the same story, even in freshly opened incognito sessions. Grid Elements had supposedly been a good solution in the past, was no longer actively developed or available for current TYPO3 versions, and had effectively been superseded by Container, which was presented as the more modern and “core-native” approach. Depending on the answer, that story came with additional claims about easier maintenance, smoother upgrades, better performance or a leaner architecture.
What made this interesting was how firmly the system defended that framing. Sometimes it provided no sources at all. Sometimes it cited material that did not support the claim, and sometimes the referenced source could not be found in the form described. Only after repeated challenges and checking the evidence ourselves would the answer occasionally reverse course and acknowledge that the original conclusion had been wrong.
We tried similar questions with Claude, Grok and ChatGPT. They were not consistently correct either, but they tended to be less persistent about the same narrative and less willing to support it with questionable evidence once asked to explain how they had reached their conclusions in the first place.
Then We Checked the Software
The claims and the code told different stories
Grid Elements is actively maintained and supports current TYPO3 versions. Container covers part of the same problem space, but deliberately implements a smaller subset of Grid Elements’ functionality and uses a substantially different data model. Neither extension is inherently more “core-native” than the other. Both extend TYPO3 where the Core itself does not provide the required functionality.
Grid Elements continues the structural concepts behind TYPO3 Backend Layouts, with roots going back to 2009 and the extension itself to 2011. Container made different choices around parent-child relationships and column handling. Those choices are legitimate, but they also require additional compatibility work around areas such as translations and TYPO3’s column mechanics that Grid Elements can handle through established Core mechanisms. We found no evidence for general claims that Container is inherently faster, leaner, easier to maintain or less demanding during upgrades.
One claim did hold up. Access to the latest Grid Elements release is tied to a paid Priority Access program, while earlier versions are publicly available through TER and packagist. Google’s AI repeatedly turned that into another claim altogether, suggesting that Grid Elements was therefore no longer open source. That is simply a category error. Open source does not mean freeware, and charging for access or distribution does not by itself make open-source software proprietary.
At that point, besides an AI that had answered a question badly, the actual problem was that this misinformation could cause real commercial harm by directly influencing how a project, and the people maintaining it, are evaluated.
The Trail Was Shorter Than Expected
AI kept finding sources we would never have looked for
The most striking example was the official TYPO3 Getting Started documentation. In a section explaining what to do when an extension is no longer available for the current TYPO3 version, it stated that Grid Elements “was replaced by the container extension, both having equal functionalities.” The wording first appeared with the TYPO3 12 documentation in 2022 and was then carried forward into the versions for TYPO3 13, TYPO3 14 and the main development branch. For somebody learning how to upgrade TYPO3 from the official documentation, there was very little reason to question it.
A large hosting provider published a Grid Elements tutorial that carried a similar message in a different form. It presented support as effectively ending with older TYPO3 versions and suggested that newer TYPO3 releases already provided native alternatives. Again, this was exactly the kind of page a newcomer might find while trying to understand whether the extension was still a sensible choice.
A third source spread the same framing across several places around its own products and documentation. Grid Elements was presented as outdated or superseded, while paid Priority Access was turned into the claim that it was no longer open source. That was particularly revealing because it took a real fact, paid access to current releases, and attached a conclusion that simply does not follow from it.
Beyond those prominent examples, the trail became much less impressive. Migration pages, project reports, comparisons and small technical remarks that many people would probably have ignored in a normal search still provided fragments that could reinforce the same narrative. Some were written later than the official documentation. That does not prove that one source copied another, but it does show that the same framing was already present in a highly authoritative source before several of the others appeared.
That was the irony. We would never have thought to read a Getting Started guide or a hosting tutorial explaining software we had worked on for years. Some of those pages could already mislead people on their own. Others would probably have remained background noise. The AI systems found both and turned them into parts of the same story.
Back to the Source
How we started setting things straight
Once we had a reasonably clear idea where the claims were coming from, the next question was fairly obvious.
What do you actually do with that knowledge?
One of the first things we did was make our own primary source more explicit. We added the relevant explanations and comparisons to the Grid Elements documentation itself, including points that, from our perspective, should never have needed spelling out in the first place. The documentation was already the most authoritative source on how Grid Elements works. What changed is that the disputed claims now have clear, directly citable answers in that same source, giving search engines, AI systems and anyone checking the facts something much harder to misinterpret.
Then we tackled the other sources one by one.
The official TYPO3 documentation turned out to be the easiest case. It is maintained openly, so there was a concrete place where the statement could be challenged and corrected. We prepared a pull request, explained why the claim that Grid Elements had been replaced by Container was factually wrong, and provided the technical background needed to support the change. There was some discussion around the correction and how far it should be carried back into older documentation versions, but the important part was straightforward. The false statement was removed.
That experience was almost reassuring. An openly maintained source gives you something tangible to work with. You can point to a sentence, provide evidence, propose better wording and have the whole discussion in the same place where the information itself is maintained. Wikipedia works on a similar principle. If a claim is demonstrably wrong and reliable evidence exists, there is at least a defined mechanism for fixing it.
The other sources were less predictable because there is no pull request button. We contacted publishers directly, sometimes through people we already knew and sometimes through a plain message explaining where the problematic statement appears and why it is inaccurate. The reactions varied considerably. One publisher went through several pages and corrected the relevant claims. Another removed an article entirely. In another case, a broad statement that had become misleading over time was narrowed down to the historical period in which it would have actually made sense. Some conversations took longer, and some depended on first finding the person who could change the page at all.
There are, of course, legal routes as well. Depending on the jurisdiction and the circumstances, false factual claims can potentially be challenged through demands for correction or removal, formal rights of reply, or other legal remedies. We deliberately did not start there. In every case we have found so far, direct contact, evidence and a reasonable opportunity to correct the record were enough. That does not make the legal options irrelevant. It simply meant we did not need them yet.
On the Radar
Watching What We Never Used to Watch
While doing this, we also started building something we had never really needed before. Several automated and AI-assisted checks now periodically look for new or changed statements about Grid Elements, collect the relevant passages and flag claims that appear to conflict with information we can verify from primary sources.
That may sound strangely obvious in hindsight. We had not been short of correct information about Grid Elements, and we had not created the incorrect claims ourselves. What we had not done was regularly search for what other people were saying about the project.
And why would we? If you have spent years developing a piece of software, you do not normally spend your evenings searching for beginner tutorials that explain it back to you. A machine can do exactly that without getting bored after the third vaguely similar migration article.
It can also get things wrong. One of our checks, for example, flagged claims about problems with responsive design and accessibility. That sounded relevant enough to investigate. Once we opened the source, however, it turned out to be talking about generic grid elements in web design, not the TYPO3 extension Grid Elements at all. Same terms, completely different subject.
That is why these systems only find candidates for inspection. They do not decide what is true, they do not contact anyone automatically, and they certainly do not publish accusations. They give us a way to notice possible problems earlier. The judgment still has to happen afterwards, with the source open, the context visible and a human checking whether there is actually something to correct.
Watch the Answer
Good search visibility is no longer enough
There is one uncomfortable lesson in all of this. Having good documentation, strong search rankings, solid SEO and even content written with AI discovery in mind does not guarantee that people will actually receive the information you published. You can rank first and still have an AI-generated summary appear above the result and tell a very different story.
So the job no longer ends with publishing accurate information and watching traffic statistics. You also have to monitor what search engines, AI systems and third-party sites are saying about you. When something questionable appears, preserve the evidence. Record when you first saw it, keep the relevant wording and context, note what you did about it and document any deadlines or responses. Our radar exists for exactly that reason.
Then start with the source, not with a lawyer. If there is a person you can talk to, talk to them. Point out the exact statement, provide verifiable evidence and make the correction as easy as possible. Our experience so far suggests that this solves more problems than opening with legal language ever would.
That does not mean the legal route is irrelevant. In May 2026, the Munich Regional Court 1 issued a preliminary injunction prohibiting Google from repeating specific false claims about two publishers in its AI Overviews, treating those generated summaries as statements attributable to Google itself. The decision is not yet final, but it shows that even an AI-generated answer at the top of a search page is not necessarily beyond legal reach.
Legal action, however, consumes time, money and attention. If a correction can be achieved with an email, a pull request or a phone call, that is usually the better first move. Monitor, document, correct and escalate only as far as necessary. And then keep monitoring. A correction can be changed again, reverted or quietly replaced later, especially in collaborative systems. Fixing the record once does not mean it will stay fixed forever.
The Record Can Change
Correcting the sources is already changing the answers
And there is an encouraging part to this story. We can already see the picture changing. ChatGPT now produces considerably more accurate answers about Grid Elements in the kinds of queries that originally sent us down this trail. Google is not there yet to the same extent, although we have started seeing changes there as well.
We cannot prove which individual correction caused which change in an AI answer, and that is probably the wrong way to look at it anyway. What we can observe is that the information environment has changed. Primary documentation now addresses the disputed claims explicitly, several misleading sources have been corrected, reframed or removed, and the answers generated from that environment are beginning to change with it.
False information can become remarkably persistent once enough systems start repeating it. Apparently, correcting the record can propagate too. It just needs someone to notice first.
But one question remains: If a handful of mostly unintentional claims can distort the picture this much, what happens when somebody does it deliberately, at scale, and keeps flooding the zone with shit until the false version is no longer an outlier, but the dominant context AI systems are most likely to find and repeat?
A handful of inaccurate or misleading sources was enough to shape surprisingly persistent AI answers about our TYPO3 extension Grid Elements, even when correct information ranked prominently in search results. We traced the claims back, strengthened our own primary documentation, contacted publishers and corrected, reframed or removed several problematic sources. The practical lesson goes beyond Grid Elements. Publishing accurate information is no longer enough. Monitor what others and AI systems say about you, preserve the evidence, correct the source whenever possible and escalate only as far as necessary. Then keep monitoring. Because the good news is that bad information may spread, but that false record is not immutable.
© Copyright 2026 Cybercraft GmbH